As a contract data engineer, I sometimes experience — ahem — let’s just say, periods of inactivity. When I browse the online market for suitable roles during those times, one of the most in-demand skills I keep seeing is experience with a tool called dbt.
So, to give myself the best possible chance of obtaining work, I decided to learn as much about dbt as I thought I needed to, to at least be confident enough to talk about it in general terms to a fellow techie at an interview stage should the need arise. This article distils that process and what I’ve learnt. Of course you can’t learn a subject just by reading about it, so as usual, I’ll show plenty of practical code and real-world examples.
To be clear, I have no affiliation or commercial association with dbt, DuckDB, or their creators.
dbt Core is a free open-source software released under the Apache 2.0 licence, and you can run it locally without a dbt account. DuckDB is also free to use under the permissive MIT licence.
dbt provides a broad range of capabilities, but as this is an introduction to the topic, I’m concentrating on explaining the basics. This includes using dbt models and sources, and using it to test data and create documentation. More about all of these later.
If you’ve worked on any reasonably sized analytics or data engineering project, you’ve probably ended up with a folder full of SQL scripts.
When your project first starts up, everything feels manageable. You run the scripts manually or schedule them in whatever orchestration tool your company uses. Everything is good.
Then the project grows.
A column gets renamed in one table, and suddenly some downstream report or dashboard stops working or, worse still, your nightly 10 million record data ingestion job fails, and your whole system grinds to a halt. The list of issues that a wrongly applied bit of SQL or a table change can do to a database system is scary. And you know what, it happens all the time.
Part of the problem is that, traditionally, SQL has been treated as a collection of isolated scripts rather than as a software project.
If this sounds all too familiar, the folks behind dbt think they have a solution.
What is dbt?
dbt (data build tool) was created in the mid 2010s by a group now known as dbt Labs. It grew from an internal analytics workflow into a widely used open-source, free (on the developer plan) CLI tool called dbt Core, alongside a fully managed, paid version called dbt Platform. I’ll be using the free version.
dbt is used to transform data already stored in a database, warehouse or lakehouse. It does this by creating tables or views based on user-supplied SQL, but it also handles the following:
Testing data quality
Documenting datasets and lineage
Reusing SQL through macros
Managing development, testing and production environments
Running transformations through scheduled jobs or CI/CD pipelines
dbt is widely used by teams operating enterprise-grade data storage platforms such as Snowflake, BigQuery, Redshift and Databricks. But for my examples, I’m going to be using a local DuckDB database.
Why do data teams use dbt?
Mainly because it’s good at what it does.
Imagine you’re building a sales reporting platform. Raw order data lands in your data warehouse every hour, say. You write one SQL script to clean the data, another to calculate customer totals, another to build daily sales figures, and another to generate executive dashboards.
At first, the project has four or five SQL files, and it’s easy to keep track of them. Six months later, there are fifty, and the order in which they run is no longer obvious.
Which script runs in which order?
What breaks if someone renames a column?
How do you check that the data is still valid?
Could a new developer understand the project without opening every SQL file?
Often, analytics teams solved these problems with naming conventions, handwritten notes passed around and a lot of shared systems knowledge.
As organisations became more data-driven, analytics projects started looking more and more like software projects. Teams needed version control, automated testing, documentation and dependency management because they were writing thousands of lines of SQL.
Rather than treating SQL scripts as independent files, dbt treats them as components of a single project, where every transformation has a defined purpose, and every dependency is understood.
Prerequisites
I’m using Windows as my operating system and have Python 3.13 installed. Everything should work in the same way if you’re on Linux or macOS but you definitely need to have Python installed. You’ll also need access to a suitable database for dbt to act on. Each database will have differences in how you set it up to use dbt. I’ll be using DuckDB as my database and will show you the set up for that. Consult the dbt docs (linked at the end) if you’re using a different data store.
Installing dbt
Now that we have a better understanding of dbt, in the rest of this article I’ll show you how to install it and, by way of example code, demonstrate the most common dbt commands you’ll use in your day-to-day job.
The first thing we should do is set up a separate Python development environment to keep our projects siloed.
PS C:\Users\thoma> cd projectsPS C:\Users\thoma\projects> mkdir dbt-demo Directory: C:\Users\thoma\projectsMode LastWriteTime Length Name---- ------------- ------ ----d----- 03/08/2026 16:21 dbt-demoPS C:\Users\thoma\projects> cd dbt-demoPS C:\Users\thoma\projects\dbt-demo> python3 -m venv .venvActual environment location may have moved due to redirects, links or junctions. Requested location: "C:\Users\thoma\projects\dbt-demo\.venv\Scripts\python3.exe" Actual location: "D:\Users\thoma\projects\dbt-demo\.venv\Scripts\python3.exe"PS C:\Users\thoma\projects\dbt-demo> .\.venv\Scripts\Activate.ps1(.venv) PS C:\Users\thoma\projects\dbt-demo>(.venv) PS C:\Users\thoma\projects\dbt-demo>(.venv) PS C:\Users\thoma\projects\dbt-demo>
You can install dbt using a simple pip command like the one shown below. To connect dbt to a data source, we use something called an adapter. dbt has many different types of adapters, for example, BigQuery, AWS Redshift, Snowflake, etc. For this demo, I’m going to be using a local DuckDB database.
Most adapters have to be installed separately from the dbt-core product, but for DuckDB, dbt provides a one-file install.
The next thing we want to do is initialise a dbt project. We do this using the dbt init command.
(.venv-core) PS C:\Users\thoma\projects\dbt-demo> dbt init15:48:36 Running with dbt=1.12.0Enter a name for your project (letters, digits, underscore): my-dbt-demomy-dbt-demo is not a valid project name.Enter a name for your project (letters, digits, underscore): my_dbt_demo15:49:02 Setting up your profile.Which database would you like to use?[1] duckdb(Don't see the one you want? https://docs.getdbt.com/docs/available-adapters)Enter a number: 115:49:05 Profile my_dbt_demo written to C:\Users\thoma\.dbt\profiles.yml using target's sample configuration. Once updated, you'll be able to start developing with dbt.15:49:05 Running dbt debug to validate the project...15:49:05 dbt version: 1.12.015:49:05 python version: 3.13.1415:49:05 python path: C:\Users\thoma\projects\dbt-demo\.venv-core\Scripts\python3.exe15:49:05 os info: Windows-11-10.0.22621-SP015:49:05 Using profiles dir at C:\Users\thoma\.dbt15:49:05 Using profiles.yml file at C:\Users\thoma\.dbt\profiles.yml15:49:05 Using dbt_project.yml file at C:\Users\thoma\projects\dbt-demo\my_dbt_demo\dbt_project.yml15:49:05 adapter type: duckdb15:49:05 adapter version: 1.10.115:49:05 Configuration:15:49:05 profiles.yml file [OK found and valid]15:49:05 dbt_project.yml file [OK found and valid]15:49:05 Required dependencies:15:49:05 - git [OK found]15:49:05 Connection:15:49:05 database: dev15:49:05 schema: main15:49:05 path: dev.duckdb15:49:05 config_options: None15:49:05 extensions: None15:49:05 settings: {}15:49:05 external_root: .15:49:05 use_credential_provider: None15:49:05 attach: None15:49:05 filesystems: None15:49:05 remote: None15:49:05 plugins: None15:49:05 disable_transactions: False15:49:05 Registered adapter: duckdb=1.10.115:49:05 Connection test: [OK connection ok]15:49:05 All checks passed!15:49:05 Your new dbt project "my_dbt_demo" was created!Initialized new project in C:\Users\thoma\projects\dbt-demo\my_dbt_demo\my_dbt_demoFor more information on how to configure the profiles.yml file,please consult the dbt documentation here: https://docs.getdbt.com/docs/configure-your-profileOne more thing:Need help? Don't hesitate to reach out to us via GitHub issues or on Slack: https://community.getdbt.com/Happy modeling!
Running the above command will create a number of folders and files. It will look something like this,
The models/example folder shows two example model files and a schema file. We’ll talk more about model files in a bit, but for now you can safely delete the entire example folder and its contents.
One of the most important files that the dbt init process creates is called profiles.yml. This holdsyour database connection properties, but you won’t see it in your dbt project structure. Instead, in Windows, its full path is,
Now we can see what dbt expects our database to be called and where it should reside. Of course, you can edit this file and change those details if you want. The path is relative to your HOME directory. I want my duckDB data file to be in,
C:\Users\thoma\projects\dbt-demo\data\my_dbt_demo
So I updated my profiles.yml file to look like this
my_dbt_demo: outputs: dev: type: duckdb path: "{{ env_var('USERPROFILE') }}/projects/dbt-demo/data/duckdb.dev" schema: raw threads: 1 prod: type: duckdb path: "{{ env_var('USERPROFILE') }}/projects/dbt-demo/data/duckdb.prod" schema: raw threads: 4 target: dev
Creating our DuckDB database
Now we can create our DuckDB database. To do that, we need to install the DuckDB CLI. Click the link below and follow the instructions relevant to your environment.
Run the duckdb CLI and pass it the name of a suitable file to permanently store your database. You can also run it without a parameter if you’re not bothered about keeping the data when you exit. Type in the following command.
Now that we have data in our database, we can start to use dbt. Two of the most important concepts to grasp in dbt are those of models and sources.
A model is simply a file containing a snippet of SQL that dbt uses to create a new table or view in your target database.
A source is an existing table or view in your data store that dbt didn’t create, such as raw data loaded by an application or ingestion tool. Sources are how models refer to existing tables in your database/schema. You define a source using a YAML configuration file. As we’re working with an orders table, we’ll call ours orders.yml.
For our example, we’re going to create a model that builds a table to hold completed orders. This will refer to our existing orders database table, so it makes sense to create a source YAML file for it. That looks like this:
# orders.ymlversion: 2sources: - name: raw schema: raw tables: - name: orders
And our model SQL file looks like this.
-- customer_orders_summary.sql{{ config(materialized='table') }}with completed_orders as ( select order_id, customer_name, order_date, quantity, quantity * unit_price as order_value from {{ source('raw', 'orders') }} where lower(order_status) = 'completed')select customer_name, count(*) as completed_order_count, sum(quantity) as total_units_purchased, round(sum(order_value), 2) as total_revenue, round(avg(order_value), 2) as average_order_value, min(order_date) as first_order_date, max(order_date) as most_recent_order_datefrom completed_ordersgroup by customer_name
Create both the model SQL file and source YAML file under the models folder in your dbt project.
Hopefully you can immediately see the benefit of using a source in our model file. Because the FROM clause in the SQL uses a reference rather than an actual table name, if the source table name were to change at some point in the future, you would only need to update that change in one place — the source file. Any and all SQLs using the source file would run unchanged.
Ok, now that those files are in place, we can run our dbt transformation. You do that using the dbt run command.
(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo> dbt run20:33:39 Running with dbt=1.12.020:33:40 Registered adapter: duckdb=1.10.120:33:40 Unable to do partial parsing because profile has changed20:33:41 [WARNING]: Configuration paths exist in your dbt_project.yml file which do not apply to any resources.There are 1 unused configuration paths:- models.my_dbt_demo.example20:33:41 Found 1 model, 1 source, 486 macros20:33:4120:33:41 Concurrency: 1 threads (target='dev')20:33:4120:33:41 1 of 1 START sql table model raw.customer_order_summary ........................ [RUN]20:33:41 1 of 1 OK created sql table model raw.customer_order_summary ................... [OK in 0.11s]20:33:4120:33:41 Finished running 1 table model in 0 hours 0 minutes and 0.23 seconds (0.23s).20:33:4120:33:41 Completed successfully20:33:4120:33:41 Done. PASS=1 WARN=0 ERROR=0 SKIP=0 NO-OP=0 REUSED=0 TOTAL=1(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo> .\duckdb $HOME\projects\dbt-demo\my_dbt_demo\data\duckdb.devDuckDB v1.5.5 (Variegata)Enter ".help" for usage hints.duckdb D show all tables;┌──────────┬─────────┬────────────────────────┬─────────────────────────────┬──────────────────────────────┬───────────┐│ database │ schema │ name │ column_names │ column_types │ temporary ││ varchar │ varchar │ varchar │ varchar[] │ varchar[] │ boolean │├──────────┼─────────┼────────────────────────┼─────────────────────────────┼──────────────────────────────┼───────────┤│ duckdb │ raw │ customer_order_summary │ [customer_name, │ [VARCHAR, BIGINT, HUGEINT, │ false ││ │ │ │ completed_order_count, │ 'DECIMAL(38,2)', DOUBLE, │ ││ │ │ │ total_units_purchased, │ DATE, DATE] │ ││ │ │ │ total_revenue, │ │ ││ │ │ │ average_order_value, │ │ ││ │ │ │ first_order_date, │ │ ││ │ │ │ most_recent_order_date] │ │ │├──────────┼─────────┼────────────────────────┼─────────────────────────────┼──────────────────────────────┼───────────┤│ duckdb │ raw │ orders │ [order_id, customer_name, │ [INTEGER, VARCHAR, VARCHAR, │ false ││ │ │ │ product_name, order_date, │ DATE, INTEGER, │ ││ │ │ │ quantity, unit_price, │ 'DECIMAL(10,2)', VARCHAR] │ ││ │ │ │ order_status] │ │ │└──────────┴─────────┴────────────────────────┴─────────────────────────────┴──────────────────────────────┴───────────┘duckdb D select * from raw.customer_order_summary;┌───────────────┬───────────────────────┬───┬─────────────────────┬──────────────────┬────────────────────────┐│ customer_name │ completed_order_count │ … │ average_order_value │ first_order_date │ most_recent_order_date ││ varchar │ int64 │ … │ double │ date │ date │├───────────────┼───────────────────────┼───┼─────────────────────┼──────────────────┼────────────────────────┤│ Charlie │ 1 │ … │ 89.0 │ 2026-02-06 │ 2026-02-06 ││ Alice │ 4 │ … │ 102.0 │ 2026-01-03 │ 2026-03-01 ││ Bob │ 1 │ … │ 59.98 │ 2026-01-04 │ 2026-01-04 ││ Diana │ 3 │ … │ 92.99 │ 2026-01-10 │ 2026-03-05 │└───────────────┴───────────────────────┴───┴─────────────────────┴──────────────────┴────────────────────────┘
The output is as expected. A new summary table is created with the required records. That’s all I’m going to say on models and sources. What I’ve shown might seem a bit of a faff for just one table, and it is, but trust me, if you are dealing with dozens or hundreds of tables and transformations, you won’t regret the time spent on creating models and sources.
Using dbt for testing your data
Another benefit of using dbt is its ability to automate your SQL testing cycle. Tests are defined (in YAML) alongside your models and sources and can be executed independently or whenever the project is built. You can write your own SQL tests, but dbt also provides four built-in test conditions:
unique
not_null
relationships
accepted_values
We’ll demo two of these tests to give you a flavour of what you can do with them.
Not null test
Our test will be run against the customer_name column of the customer_order_summary table. As we’re testing a table that dbt is creating, we add the test YAML to a models section in our orders.yml file. It now looks like this:
Now, to run our test, we can simply type the dbt build command like this, which runs and validates the selected parts of a dbt project in dependency order.
(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo> dbt build08:43:19 Running with dbt=1.12.008:43:20 Registered adapter: duckdb=1.10.108:43:20 [WARNING]: Configuration paths exist in your dbt_project.yml file which do not apply to any resources.There are 1 unused configuration paths:- models.my_dbt_demo.example08:43:20 Found 1 model, 1 test, 1 source, 486 macros08:43:2008:43:20 Concurrency: 1 threads (target='dev')08:43:2008:43:20 1 of 2 START sql table model raw.customer_order_summary ........................ [RUN]08:43:20 1 of 2 OK created sql table model raw.customer_order_summary ................... [OK in 0.14s]08:43:20 2 of 2 START test not_null_customer_order_summary_customer_name ................ [RUN]08:43:20 2 of 2 FAIL 1 not_null_customer_order_summary_customer_name .................... [FAIL 1 in 0.02s]08:43:2008:43:20 Finished running 1 table model, 1 test in 0 hours 0 minutes and 0.24 seconds (0.24s).08:43:2008:43:20 Completed with 1 error, 0 partial successes, and 0 warnings:08:43:2008:43:20 [ERROR]: in test not_null_customer_order_summary_customer_name (models\orders.yml)08:43:20 Got 1 result, configured to fail if != 008:43:2008:43:20 compiled code at target\compiled\my_dbt_demo\models\orders.yml\not_null_customer_order_summary_customer_name.sql08:43:2008:43:20 Done. PASS=1 WARN=0 ERROR=1 SKIP=0 NO-OP=0 REUSED=0 TOTAL=2
The issue is caught and reported on. dbt doesn’t delete or roll back a model when its subsequent data test fails. However, models downstream of the failed test are normally skipped during the build. If you want to run the test without re-creating any tables, etc., just use the dbt test command.
Accepted values test
This does exactly what it sounds like. It enables you to test that a column contains only specific values. If we look at our orders table, we can see that the order_status column should only contain either completed,processing, returned or cancelled values. So let’s update the table and change one of the values to be something else.
duckdb D select * from raw.orders where order_id = 10;┌──────────┬───────────────┬──────────────┬────────────┬──────────┬───────────────┬──────────────┐│ order_id │ customer_name │ product_name │ order_date │ quantity │ unit_price │ order_status ││ int32 │ varchar │ varchar │ date │ int32 │ decimal(10,2) │ varchar │├──────────┼───────────────┼──────────────┼────────────┼──────────┼───────────────┼──────────────┤│ 10 │ Bob │ Mouse │ 2026-02-14 │ 1 │ 24.99 │ cancelled │└──────────┴───────────────┴──────────────┴────────────┴──────────┴───────────────┴──────────────┘duckdb D update raw.orders set order_status = 'invalid' where order_id = 10;duckdb D select * from raw.orders where order_id = 10;┌──────────┬───────────────┬──────────────┬────────────┬──────────┬───────────────┬──────────────┐│ order_id │ customer_name │ product_name │ order_date │ quantity │ unit_price │ order_status ││ int32 │ varchar │ varchar │ date │ int32 │ decimal(10,2) │ varchar │├──────────┼───────────────┼──────────────┼────────────┼──────────┼───────────────┼──────────────┤│ 10 │ Bob │ Mouse │ 2026-02-14 │ 1 │ 24.99 │ invalid │└──────────┴───────────────┴──────────────┴────────────┴──────────┴───────────────┴──────────────┘
As we’re testing a source table, we should put our test YAML config in the sources section of our YAML file. You can leave or remove the original null test if you want. I’ve kept it in.
We’re running the test on an existing table, so we don’t need to run the build command. We can just use dbt test.
(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo> dbt test09:08:04 Running with dbt=1.12.009:08:04 Registered adapter: duckdb=1.10.109:08:04 [WARNING]: Configuration paths exist in your dbt_project.yml file which do not apply to any resources.There are 1 unused configuration paths:- models.my_dbt_demo.example09:08:04 Found 1 model, 2 data tests, 1 source, 486 macros09:08:0409:08:04 Concurrency: 1 threads (target='dev')09:08:0409:08:04 1 of 2 START test not_null_customer_order_summary_customer_name ................ [RUN]09:08:04 1 of 2 FAIL 1 not_null_customer_order_summary_customer_name .................... [FAIL 1 in 0.03s]09:08:04 2 of 2 START test source_accepted_values_raw_orders_order_status__completed__processing__returned__cancelled [RUN]09:08:04 2 of 2 FAIL 1 source_accepted_values_raw_orders_order_status__completed__processing__returned__cancelled [FAIL 1 in 0.02s]09:08:0409:08:04 Finished running 2 data tests in 0 hours 0 minutes and 0.11 seconds (0.11s).09:08:0409:08:04 Completed with 2 errors, 0 partial successes, and 0 warnings:09:08:0409:08:04 [ERROR]: in test not_null_customer_order_summary_customer_name (models\orders.yml)09:08:04 Got 1 result, configured to fail if != 009:08:0409:08:04 compiled code at target\compiled\my_dbt_demo\models\orders.yml\not_null_customer_order_summary_customer_name.sql09:08:0409:08:04 [ERROR]: in test source_accepted_values_raw_orders_order_status__completed__processing__returned__cancelled (models\orders.yml)09:08:04 Got 1 result, configured to fail if != 009:08:0409:08:04 compiled code at target\compiled\my_dbt_demo\models\orders.yml\source_accepted_values_raw_ord_0932c13ab9fb3a73a9e3e3c87c81af50.sql09:08:0409:08:04 Done. PASS=0 WARN=0 ERROR=2 SKIP=0 NO-OP=0 REUSED=0 TOTAL=2(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo>
The other two types of built-in test are equally easy to set up and run, so I’ll leave it at that.
Using dbt to document your system
The final introductory dbt topic we’re going to look at is arguably one of its best features. Most documentation starts life with good intentions before quietly becoming out of date. dbt approaches documentation differently.
Because your models, tests and metadata all live alongside your SQL, dbt can generate project documentation automatically. More importantly, it also creates a visual lineage graph showing exactly how your models depend on one another.
This is invaluable when someone new joins your project because they don’t need to reverse-engineer hundreds of SQL files. They can see the entire transformation pipeline almost immediately.
It’s one of those features that doesn’t seem particularly exciting until you’ve inherited someone else’s analytics project.
Right off the bat, dbt can do some automated documentation for you, but it’s one of those things that the more you put into it, the better documentation you will get out. Without doing anything extra to our project, here is the bare documentation you get. We use the dbt docs generate command to create the documentation like this.
(.venv-core) PS C:\Users\thoma\projects\dbt-demo\my_dbt_demo> dbt docs generate09:21:19 Running with dbt=1.12.009:21:19 Registered adapter: duckdb=1.10.109:21:19 [WARNING]: Configuration paths exist in your dbt_project.yml file which do not apply to any resources.There are 1 unused configuration paths:- models.my_dbt_demo.example09:21:19 Found 1 model, 2 data tests, 1 source, 486 macros09:21:1909:21:19 Concurrency: 1 threads (target='dev')09:21:1909:21:19 Building catalog09:21:19 Catalog written to C:\Users\thoma\projects\dbt-demo\my_dbt_demo\target\catalog.json
Now that we’ve generated the documentation, we can visualise it in a web browser using the dbt docs serve command.
You should see a browser window open that looks something like this,
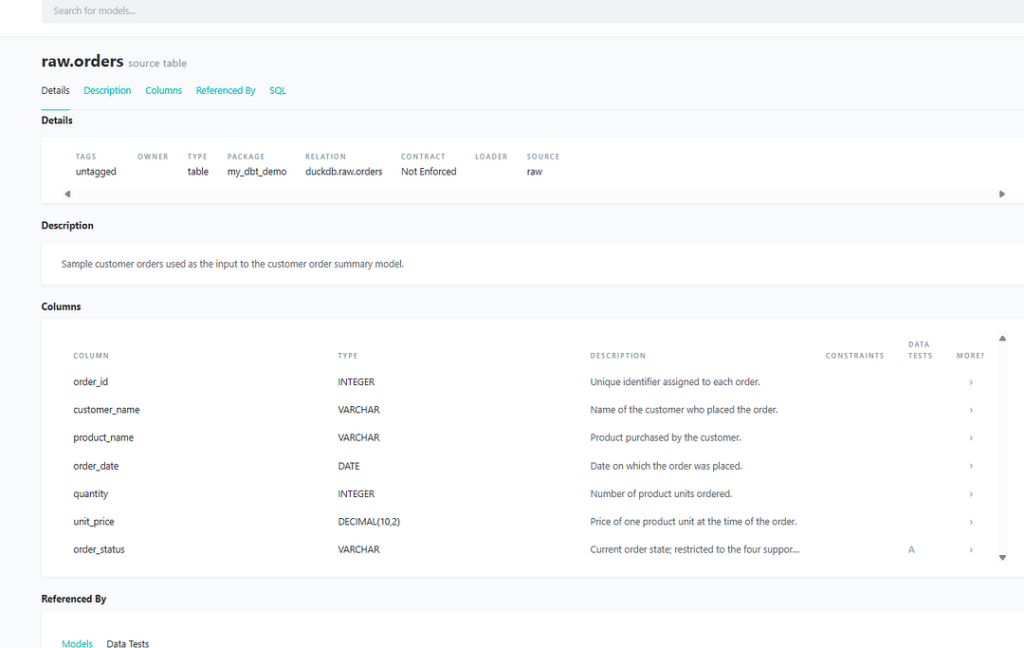
As I mentioned, it’s pretty bare-bones but nonetheless useful. To see the real power, you have to add your own descriptive documentation text in the form of YAML to your orders.yml file. Here is an example.
version: 2sources: - name: raw description: "Raw demonstration data created directly in DuckDB before dbt transformations run." schema: raw tables: - name: orders description: "Sample customer orders used as the input to the customer order summary model." columns: - name: order_id description: "Unique identifier assigned to each order." - name: customer_name description: "Name of the customer who placed the order." - name: product_name description: "Product purchased by the customer." - name: order_date description: "Date on which the order was placed." - name: quantity description: "Number of product units ordered." - name: unit_price description: "Price of one product unit at the time of the order." - name: order_status description: "Current order state; restricted to the four supported status values." data_tests: - accepted_values: arguments: values: - completed - processing - returned - cancelledmodels: - name: customer_order_summary description: > A dbt-created table containing one row per customer. It includes only completed orders and summarises order counts, units purchased, revenue and order dates. columns: - name: customer_name description: "Customer represented by the summary row." data_tests: - not_null - name: completed_order_count description: "Number of completed orders placed by the customer." - name: total_units_purchased description: "Total number of units across the customer's completed orders." - name: total_revenue description: "Total value of the customer's completed orders." - name: average_order_value description: "Average value of the customer's completed orders." - name: first_order_date description: "Earliest completed order date for the customer." - name: most_recent_order_date description: "Most recent completed order date for the customer."
Now, when we run the two dbt documentation commands, we get a much richer output like this.
Next stages
dbt is a large ecosystem, and as I explained, I only wanted to touch on some of the basics of its operation. As things stand, I’m happy with the knowledge I have on using dbt. If you want to take things further, you might want to dive deeper into the following topics, which build on what I’ve talked about here.
Incremental models: Process only new or changed records instead of rebuilding an entire table on every run.
Jinja: A templating language that lets you add variables, conditions, loops and reusable functions to SQL.
Macros: Reusable pieces of Jinja and SQL logic that can accept parameters and generate SQL.
Snapshots: Record how source records change over time, allowing you to retain their historical values.
Reusable packages: Use models, macros and tests created by other dbt projects instead of building everything yourself.
Here is a link to the official dbt Labs home page where you’ll find all the information you need to know about dbt.